
An AI SEO Crawl Audit Checklist for Publishers
Use this AI SEO crawl audit checklist to check crawler access, rendering, sitemaps and paywalls, then prioritize fixes and measure publisher outcomes.
An AI SEO crawl audit checks whether search engines and AI search systems can discover, retrieve and interpret the articles you want readers to find. For publishers, that means looking beyond broken links. A successful HTTP response can still hide an empty article shell, an incorrect canonical or a bot challenge that prevents access.
This checklist focuses on technical evidence: URL inventories, crawl responses, rendered content, indexing controls and server logs. Use it to identify access problems without confusing crawler access with guaranteed indexing, rankings or AI citations.
Before crawling, define your publishing policy
Decide which content should be available to which systems before changing robots.txt. Public reporting, subscriber articles, licensed wire stories and account pages may require different treatment. Your commercial and licensing policies should determine access, not a blanket recommendation to allow every crawler.
Separate three purposes: search discovery, user-requested retrieval and model training. These are not interchangeable. A publisher may want articles discoverable in an AI search product while restricting a separate training crawler, where the provider offers those controls.
For this AI SEO audit, record the intended treatment of each major content type. Include whether the article should appear in search, whether a public preview is available and whether training access is permitted.
Set the crawl scope and limits, too. Capture representative news articles, evergreen guides, section pages, author profiles, subscriber content and older archives. Include different CMS templates and recently migrated sections. Agree on a request rate that will not disrupt publishing infrastructure, and use a staging environment for potentially disruptive tests.
Pass condition: Every content class has an explicit access policy and an owner who can approve changes.
AI SEO crawl audit checklist
Work through these checks in order. Save evidence for each failure so developers can reproduce it rather than interpret a crawler’s warning label.
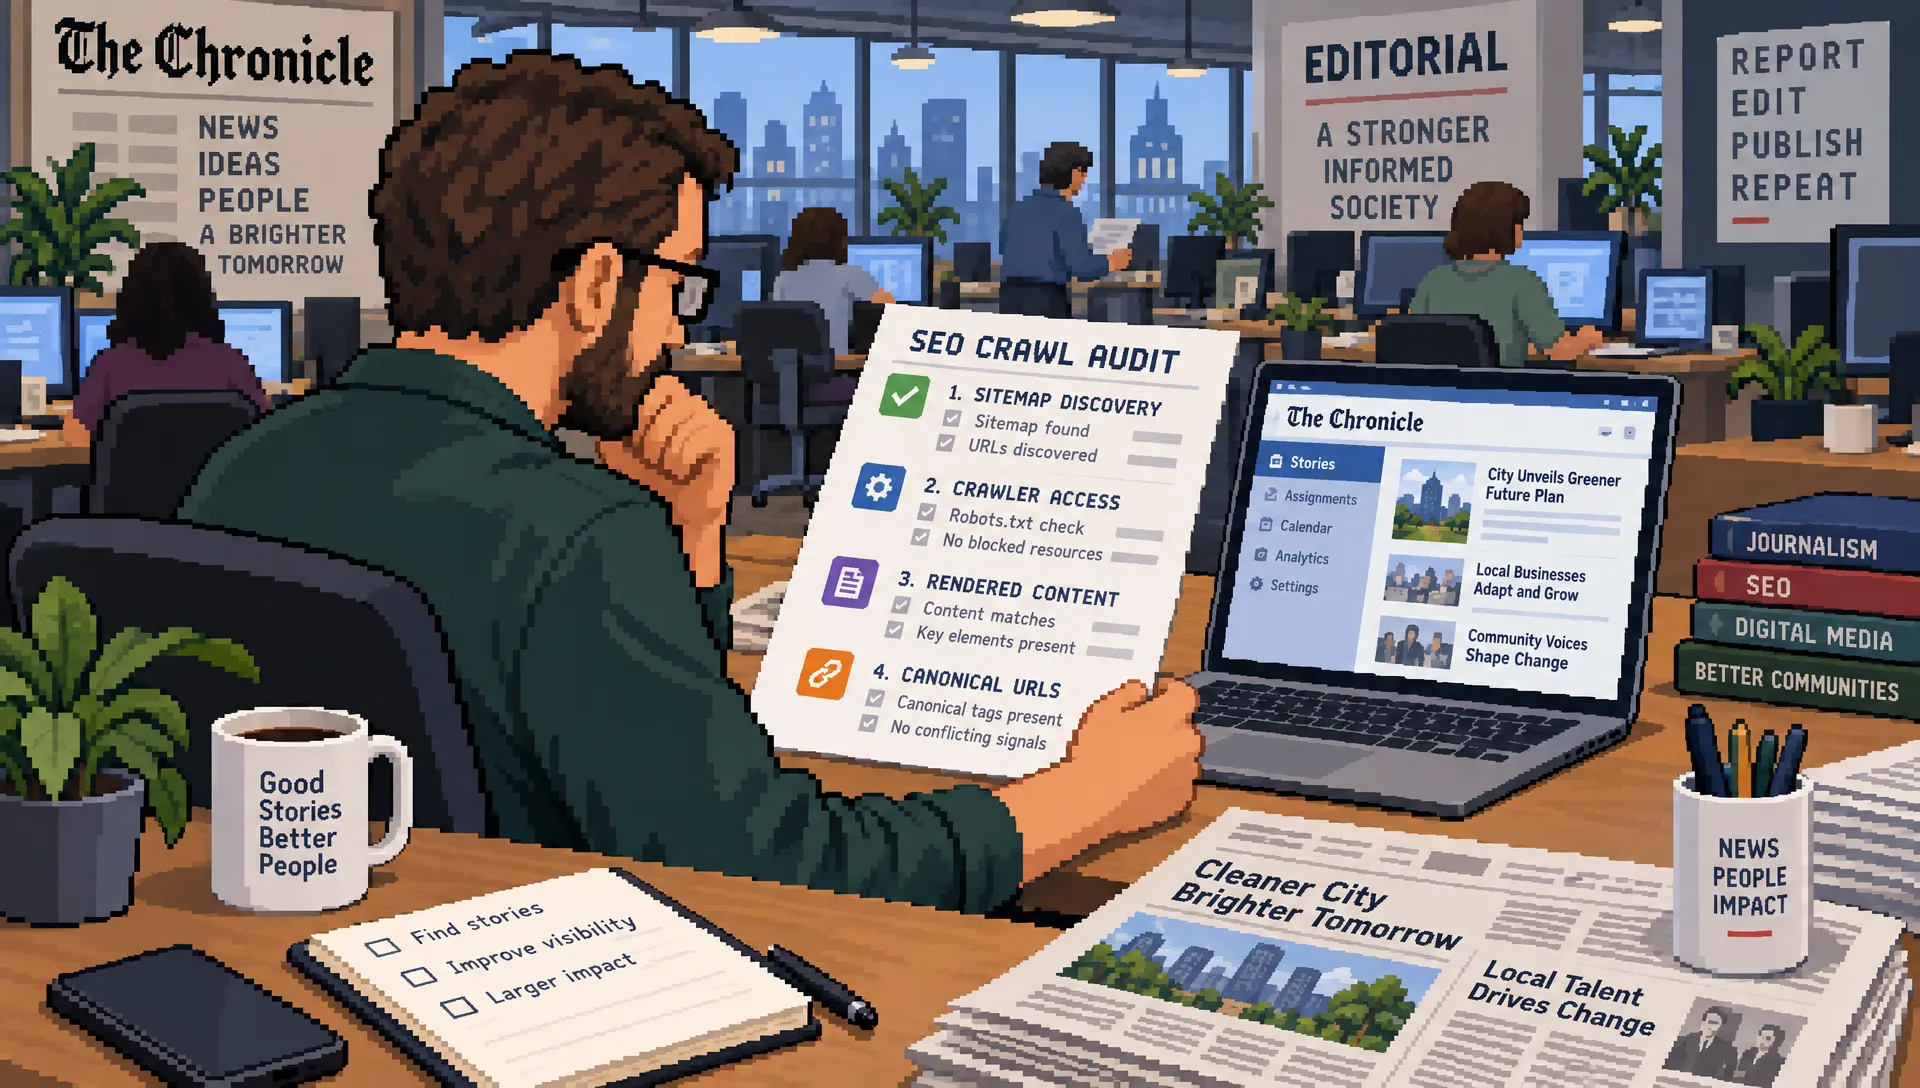
1. Reconcile the URL inventory and XML sitemaps
Start with a CMS export of articles that should be publicly discoverable. Compare it with XML sitemaps, URLs found through internal links and available search performance data. Each source reveals something different: the CMS shows publishing intent, while a crawl shows what links actually expose.
Inspect sitemap entries for redirects, errors, noncanonical URLs and articles intentionally excluded from search. Check whether recently published stories appear through the expected process. Where lastmod is present, it should reflect a meaningful page modification rather than the time the sitemap was regenerated.
For a concrete XML inspection exercise, this public sitemap provides a mixed-site example to compare with your own inventory. Classify entries by page type rather than assuming every listed URL deserves the same crawl priority.
An AI SEO inventory should also expose orphaned articles: published URLs absent from the internal link crawl. Sitemap inclusion can help discovery, but it does not replace useful navigation or guarantee indexing.
Check article pagination, archive depth and links from section pages. A valuable investigation buried beyond inaccessible archive controls may technically exist without being easy to discover.
Pass condition: Intended articles appear in the appropriate discovery paths, and exclusions or discrepancies have documented reasons.
2. Review crawler permissions by purpose
Fetch robots.txt from every relevant hostname, including separate news, image or archive hosts. Inspect the rules that apply to each crawler rather than reading only the wildcard group. Confirm how your robots parser handles matching groups and path rules.
For OpenAI, distinguish OAI-SearchBot, GPTBot and ChatGPT-User. The official crawler documentation describes their different search, training and user-requested functions. Do not assume that changing one agent’s permissions changes the others. User-requested fetching also should not be treated as identical to automatic crawling.
For Google, distinguish Googlebot from Google-Extended. Google explains in its AI features documentation that existing Search controls apply to AI features in Search. Google-Extended is not the control for inclusion in Google Search.
In an AI SEO permissions review, evaluate robots rules alongside CDN rules, firewall policies and rate limits. A crawler allowed by robots.txt can still receive an access-denied response at the edge. Conversely, allowing a user-agent string through a firewall without verification can admit impersonators.
Record the policy decision, relevant documentation and the date checked. Provider behavior can change, so an old spreadsheet is not sufficient evidence.
Pass condition: Crawler permissions match your approved policy across robots.txt and infrastructure controls, with training and search decisions recorded separately.
3. Test HTTP responses and indexing directives together
Request representative URLs and inspect the entire response chain. Record status codes, redirect destinations, content types, robots meta tags and X-Robots-Tag headers. Include PDFs or other indexable assets if they contribute to your publication’s visibility.
A 200 response does not prove that an article is accessible. Some systems return challenge pages, consent screens or soft-error messages with successful status codes. Inspect the returned content, not just the status column.
Check for contradictions between robots.txt and indexing directives. As Google’s robots.txt guidance explains, blocking crawling is not a reliable way to prevent a URL from appearing in search. A crawler generally needs access to discover a page-level noindex directive.
Your AI SEO findings should distinguish “cannot fetch” from “can fetch but should not index.” These require different fixes. Also inspect nosnippet, max-snippet and data-nosnippet where relevant to Google, since preview restrictions can affect how content is available for Search features.
Test deliberate exclusions as carefully as public articles. Robots rules are not authentication and must not be used to protect private documents, account data or unpublished stories.
Pass condition: Responses and directives consistently express the intended treatment, without accidental blocks, hidden errors or privacy assumptions.
4. Compare source HTML with rendered articles
Fetch the original response HTML, then compare it with the page after browser rendering. Check the headline, article body, byline, publication date, update date and links. A page that looks complete in your browser may initially deliver little more than a JavaScript shell.
Do not assume every retrieval system executes JavaScript or waits for the same resources as a browser. Identify which essential elements depend on client-side requests, hydration or user interaction. Test what happens when a script fails or loads slowly.
For this part of the AI SEO audit, compare actual extracted text across several templates. Look for missing paragraphs, duplicated recommendation modules, newsletter prompts inserted between sentences and captions detached from their images. Extraction quality matters even when the page is technically accessible.
Consent interfaces deserve a separate check. Confirm that the behavior complies with your privacy requirements while avoiding accidental delivery of an empty page or a consent-only response to permitted crawlers. Do not solve retrieval issues by silently bypassing legal obligations.
Prefer semantic article structure and accessible navigation over crawler-specific rewrites. Clear headings, meaningful links and text-based information help readers as well as machine extraction.
Pass condition: The permitted response contains the intended article text in a coherent order, with no critical dependency left untested.
5. Resolve canonical, syndication and archive conflicts
Inspect declared canonicals and compare them with sitemap URLs, internal links and redirect destinations. Check whether protocol, hostname, trailing-slash and tracking-parameter variants converge on the intended article URL. Canonicals are signals, not a promise that a search engine will select your preferred version.
Publishers should pay particular attention to syndicated stories, print views, republished archives and regional editions. A template-level canonical mistake can affect thousands of articles while leaving each page looking normal to an editor.
An AI SEO crawl should flag conflicting signals rather than prescribe one universal syndication rule. Your licensing agreements, editorial ownership and distribution goals determine the appropriate treatment. Document the intended primary version before making bulk changes.
Review internal links as well. If section pages repeatedly point to redirected or nonpreferred variants, fix the link source rather than relying indefinitely on redirects. Avoid automatically consolidating distinct reporting simply because articles share a topic or headline language.
Check migrated archives against their redirect map, including valuable articles with older URL patterns. A redirect to an unrelated category page is not equivalent to preserving the original story.
Pass condition: Canonicals, redirects, sitemaps and internal links support the intended versions, with justified exceptions recorded.
6. Verify article identity, dates and paywall treatment
Check whether readers and retrieval systems can identify who wrote an article, when it was published and whether it has materially changed. Inspect visible bylines, linked author profiles, publication dates and update labels across templates.
Compare any Article or NewsArticle structured data with the visible page. Headline, author, dates and image references should describe the actual article. Validate the markup, but do not confuse valid syntax with accurate information or guaranteed search features.
This AI SEO check is about consistency, not adding unsupported claims to markup. Do not invent credentials, rewrite publication dates to suggest freshness or mark promotional material as independent reporting. Keep corrections and substantial updates clear to readers.
For subscriber articles, inspect the publicly available portion and access controls. Google provides structured data guidance for paywalled content, which publishers can use where applicable. That guidance does not establish how every AI provider will handle the same page.
Confirm that public previews do not accidentally expose protected article text through an API response, embedded payload or alternate URL.
Pass condition: Visible identity, timestamps and markup agree, and paywall implementation matches both access policy and the applicable search requirements.
7. Verify crawler access in logs and constrain AI analysis
A desktop crawler test shows what your test client received. Server and CDN logs help establish what real requests received. Review status codes, requested paths, response sizes, challenge outcomes and rate-limit events over a representative period.
A claimed user agent is not proof of identity. Verify requests using the provider’s published methods, such as documented IP ranges or DNS verification where available. Label unverified traffic separately. If the CDN blocks a request before it reaches the origin, origin logs alone will miss that event.
AI SEO analysis becomes more useful when each finding points to a URL, timestamp and reproducible observation. A model can group repeated failures or summarize template patterns, but it should not invent a root cause from a status code. Require a manual test before accepting recommendations.
If you use a model to review exports, remove credentials, personal information, signed URLs and sensitive query parameters. Minimize or pseudonymize identifiers, check retention settings and use an approved account. Treat fetched page text as untrusted data, not instructions the model should follow.
The workflow for using OpenAI models for evidence-based SEO audits provides a useful companion for structuring traceable findings.
Pass condition: Important failures have verified evidence, and automated analysis respects your data-handling requirements.
8. Retest fixes and measure publisher outcomes
Keep a stable test set spanning your main templates and content policies. After a fix, rerun the same requests and compare response content, directives, canonical targets and extraction results. Then test additional URLs to check whether the change generalizes.
Maintain a change log with deployment dates and affected templates. Watch for regressions after CMS releases, consent-platform changes, CDN updates and paywall experiments. A previously clean crawl does not establish that the current production configuration is still correct.
Measure AI SEO work in layers. First track technical outcomes, such as fewer unintended blocks or more complete article extraction. Then inspect available indexing and search performance data. Finally evaluate reader outcomes, including qualified visits, newsletter subscriptions and paid conversions where attribution is available.
For citation monitoring, use a fixed set of relevant questions and record the platform, date, locale and cited URL. Repeat observations because answers can vary. A single appearance or disappearance is not reliable evidence of an audit’s effect.
Do not relabel unexplained direct traffic as AI traffic or assume every citation produces a visit. Where practical, compare repaired templates with similar unchanged templates while accounting for news cycles and publication volume.
Pass condition: The fix survives retesting, and technical improvements are reported separately from visibility and business results.
Prioritize findings by impact and confidence
The most useful audit output is a repair queue, not a collection of warnings. Assign each issue an owner, affected URL count, evidence link, expected impact and retest procedure. Separate observed failures from hypotheses requiring investigation.
Use the following as a starting framework, then adjust it to your publication’s access policy and commercial priorities.
| Finding | Suggested priority | Evidence required |
|---|---|---|
| Protected content exposed publicly | Critical | Reproducible unauthorized access |
| Intended public article templates blocked | High | Response samples and affected scope |
Widespread wrong canonical or noindex |
High | Template checks and URL examples |
| Important articles orphaned internally | Medium | Inventory and internal-link comparison |
| Minor optional markup inconsistency | Lower | Validation result and visible-page comparison |
An AI SEO audit should prioritize proven access failures before speculative citation enhancements. A missing optional property rarely deserves attention ahead of a firewall rule preventing an entire article template from being retrieved.
Use existing tools first: CMS exports, a crawler, browser inspection, search reporting and log analysis often cover the core checks. Add specialist software only when it supplies evidence or monitoring you cannot obtain efficiently. No tool score should replace inspection of the underlying response.
Frequently asked questions
Does allowing an AI crawler guarantee citations? No. Access is one prerequisite for retrieval, not a guarantee of selection or citation. Relevance, available sources and platform-specific behavior still affect what appears in an answer.
Is there a special schema required for Google’s AI features? Google says no special structured data is required for its AI Search features. Follow the applicable indexing, snippet and structured data guidance rather than adding unsupported “AI citation” markup.
Do publishers need an llms.txt file? Do not treat it as a prerequisite for discovery or as an access-control mechanism. Follow documented provider requirements and prioritize verified crawling, indexing and extraction problems first.
How often should an AI SEO crawl audit run? Run a baseline audit, retest after consequential infrastructure or template changes and monitor high-impact failures between full reviews. The appropriate cadence depends on publishing volume, platform stability and the cost of an unnoticed regression.
Turn the checklist into a repeatable review
Choose one representative article from each major template and establish the expected response before scaling up. Fix shared problems at the template or infrastructure level, preserve the evidence and rerun the same tests after deployment.
Once access is dependable, connect those findings to your broader strategy for visibility in ChatGPT, Perplexity and Google AI. Reliable retrieval gives that strategy a technical foundation, without promising citations that no crawl audit can guarantee.
Read more
How OpenAI Search Handles Paywalls and Subscriber Content
A paywalled article can appear in an AI answer without its full text being available. Learn how citations, publisher agreements and crawler controls differ, then protect subscriber content without hiding every useful preview.
How to Manage Your Privacy in ChatGPT Search
Turning off model training does not make web searches anonymous or erase saved information. Learn which settings control memory, location and chat retention, plus what to check before opening a result or searching with work data.
How ChatGPT and Google Handle Fresh Information
An answer can sound current while relying on old evidence. Learn how each platform finds updates, how to check time-sensitive claims and what publishers can do to make genuine changes easier to discover.